
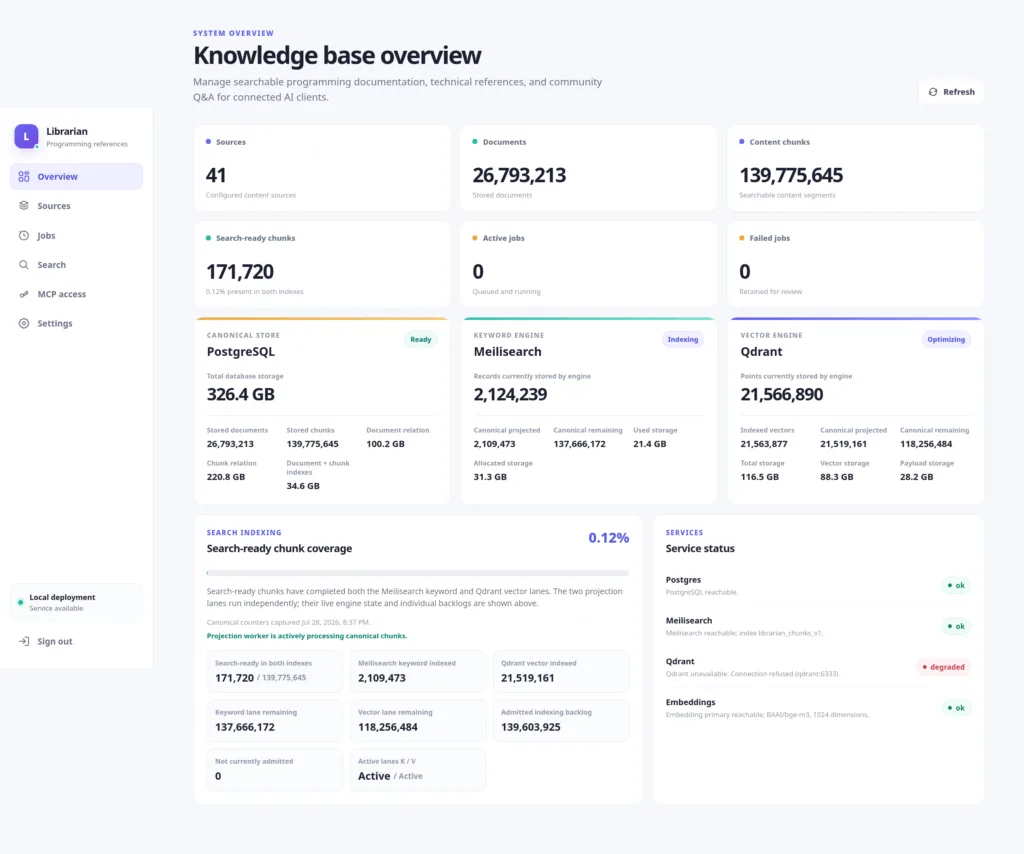
I’ve spent quite a bit of time on a side project that basically serves as my own private search engine for programming documentation and other public information.
At first, I thought, “This is just under 200 GB of data. My 2 TB NVMe can handle it.”
That has proven to be one of the most wildly underestimated thoughts I’ve ever had.
Granted, I barely knew anything about RAG when I started. My knowledge has since evolved from “How do I hoard even more data?” to “How do I compress all of this without destroying its usefulness?”
Honestly, it has been quite the project.
It works, by the way. I process the data locally using my RTX 3090, generate the embeddings, index the vectors, and then search across everything in a matter of milliseconds. The results are fast, relevant, and scored far better than a basic keyword search.
Now the challenge is no longer getting the information in.
It is figuring out how much of it I can remove without making the system worse.
It’s been a set of hard-learned lessons. I do hope to use this more when there are power outages, or when I need to research something locally.